Voice Recognition
AI-powered voice recognition software utilizes advanced algorithms to convert spoken language into text, offering significant advantages in various sectors. It aids individuals with disabilities, enhances in-car systems, facilitates military operations, and supports efficient business processes through dictation and transcription.
Sort by:
53 results

OpenMusicPrompt is an all-in-one AI music studio that helps users analyze, generate, and perfect original music. It offers tools like AI lyrics and music generators, song cover creators, and prompt optimizers, streamlining the music production process for creators of all levels.
OmniVoice is an AI voice generation tool that supports natural speech in 646 languages. It features zero-shot voice cloning, allowing users to replicate voices from short audio samples without training. Additionally, it enables custom voice creation based on text descriptions, making it versatile for various applications.

Enhances audio by identifying and removing background noise, increasing clarity of human speech in audio files.

Advanced vocal technology platform offering high-quality voice cloning and emotion recognition.

Transcription, subtitling, and voiceover services for audio and video files. It enables users to efficiently create and edit captions, voiceovers, and transcripts in multiple languages.

An AI text-to-speech model offering efficient, multilingual voice synthesis with customizable voicepacks for various applications.

Kits AI is an AI voice generation platform for creating and using AI voices, enabling musicians to produce and transform vocals without needing live session artists.

Motion-2 is an AI lip-sync model by JoyPix.ai to create realistic and precise talking videos using still photos with features like voice cloning and avatar generation.

Higgs Audio is an advanced AI-powered text-to-speech platform featuring zero-shot voice cloning and high-fidelity 24kHz audio generation.

Automated testing & monitoring platform for AI voice agents, providing simulation and analytics for diverse scenarios and languages.
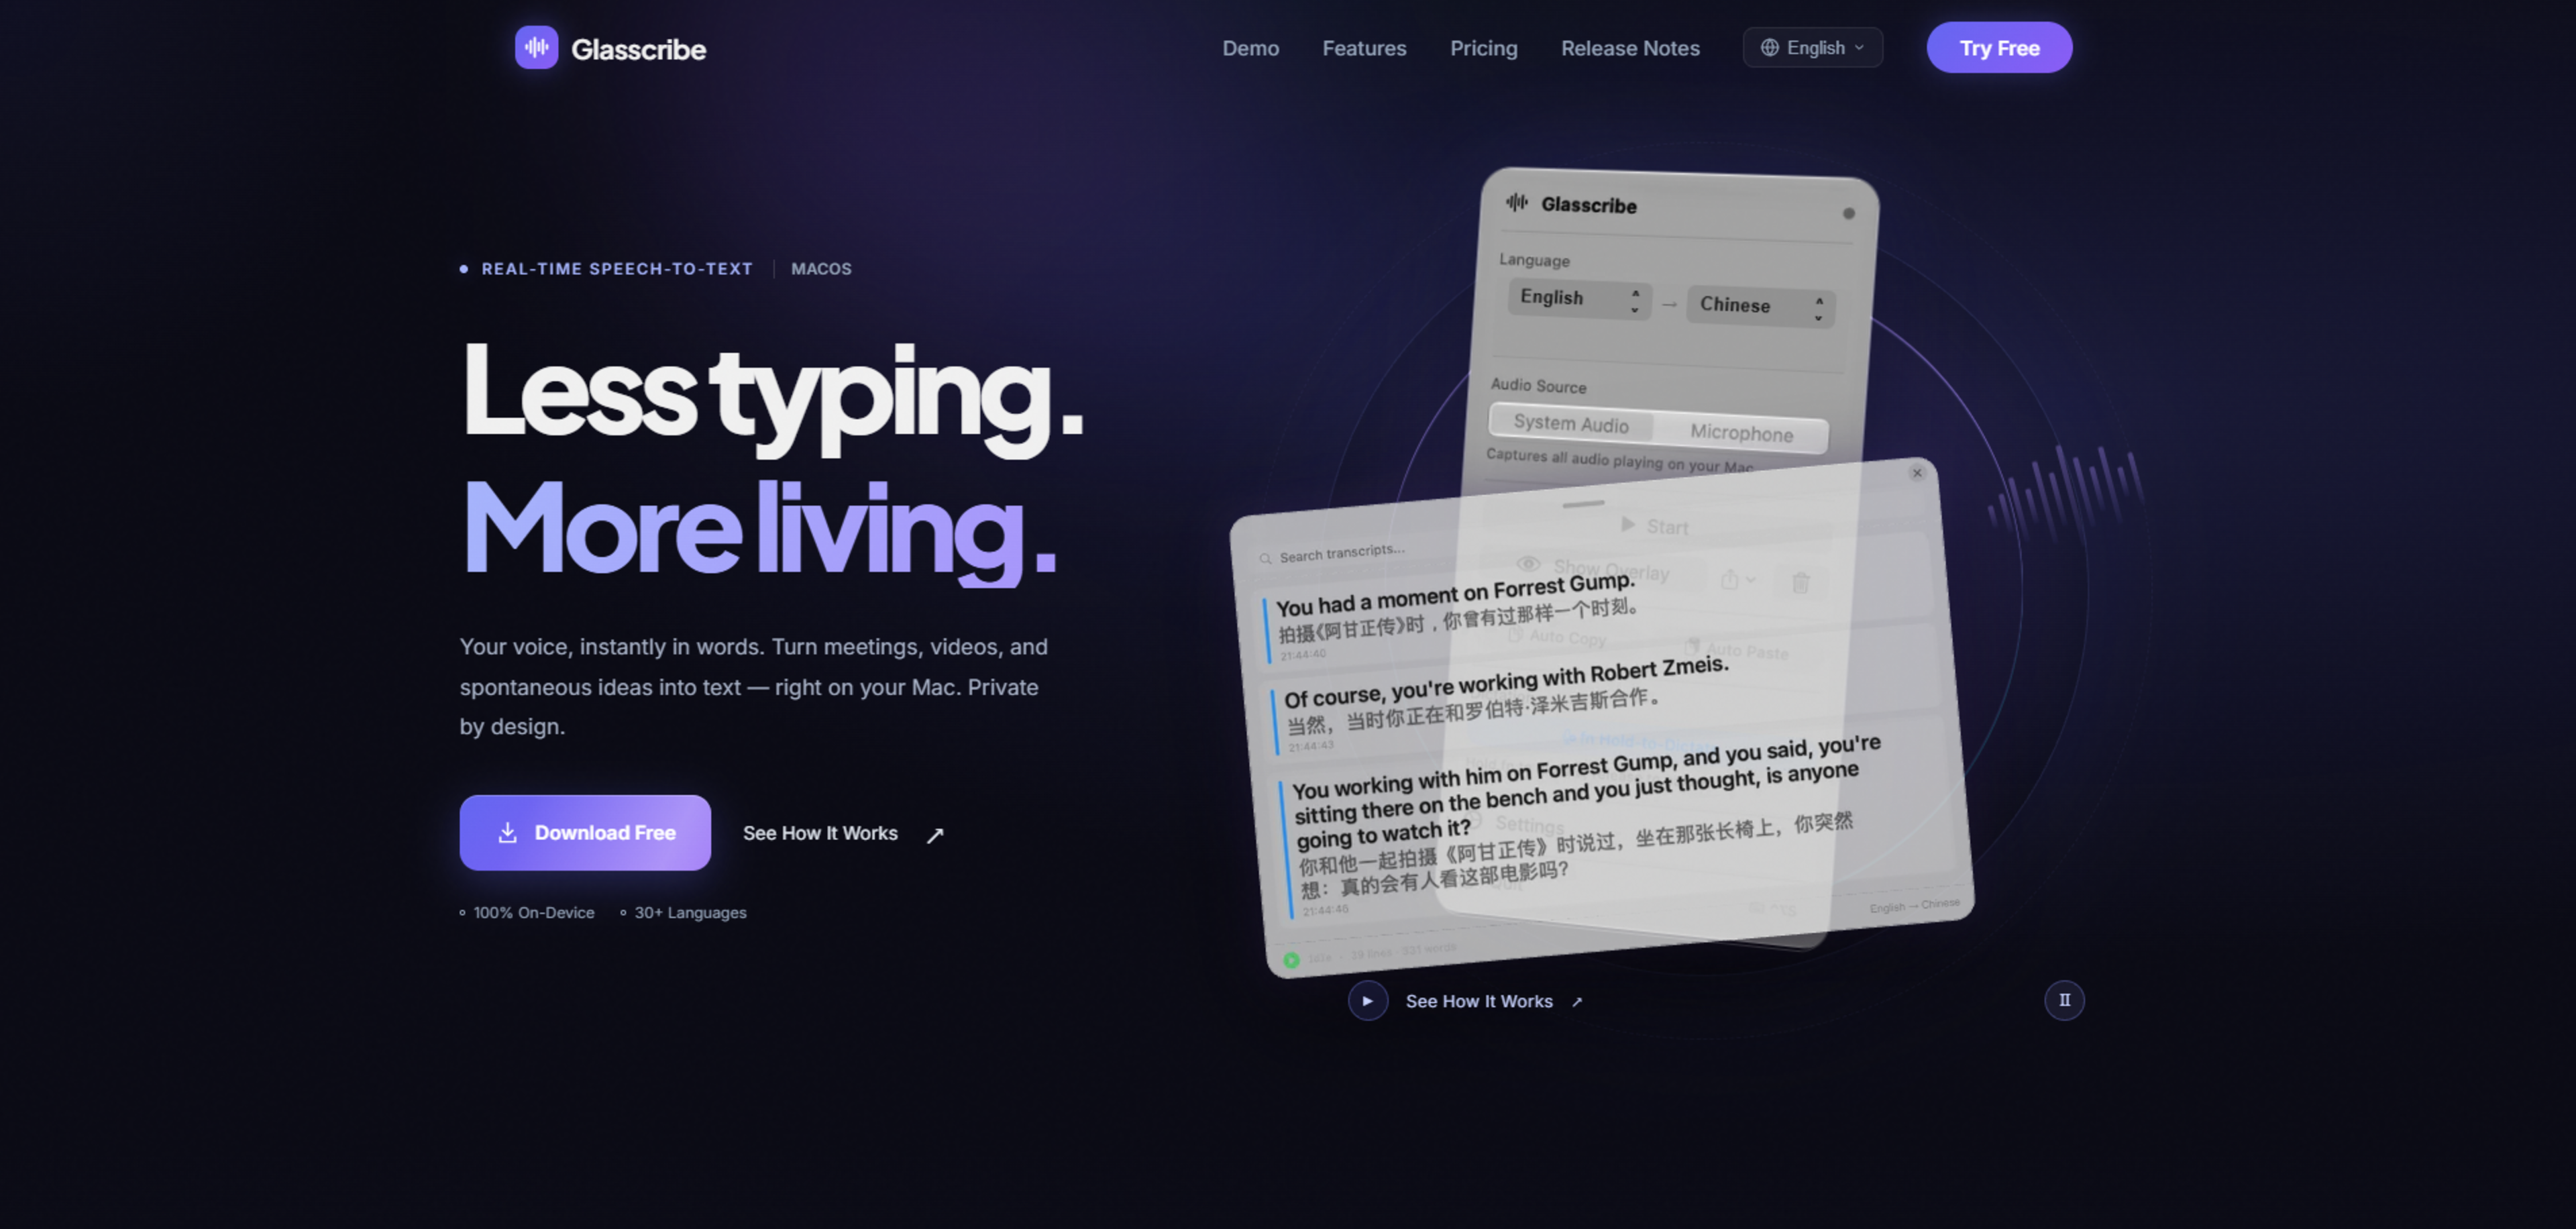
Glasscribe is a macOS app that provides real-time, on-device speech-to-text transcription. It supports 30+ languages and live translation, capturing audio directly from your system without the need for internet connectivity. Features include a floating overlay, session history, and automatic copying of transcribed text.

A free online service that creates a digital replica of a human voice from a short audio sample for use in various applications.

Fluxon is an AI-driven ultrarealistic voice generator that transforms text into lifelike audio with hyper-realistic voices in multiple languages.

Voice AI platform for automating calls, handling inbound and outbound tasks, and custom integrations with enterprise reliability.

FlowSpeech is a context-aware text-to-speech tool that converts text into lifelike audio using human-like voices. It features emotion delivery, precise pause controls, and supports multiple speakers for professional-quality audio generation, making it ideal for content creators and marketers.

AI-powered personal singing teacher to improve singing skills
Echonova AI is an advanced music generation platform that allows users to create original tracks and lyrics from prompts in minutes. It features tools like vocal removal, stem splitting, and sound effects generation, making music production accessible for everyone, whether beginners or professionals.

DubSmart offers lifelike text-to-speech, voice cloning for dubbing, and speech-to-text services for video translation in over 30 languages.

Easily generate custom drum loops in a variety of genres with AI technology.

Converts text to lifelike speech with customizable AI voices across various languages and dialects, enabling rapid production of voiceovers for multiple applications.

Generate celebrity-like voices using AI for free.

AudioX is an AI-powered platform for converting text, images, and videos into professional audio, such as music, sound effects, and voice content.

Audio Enhancer is an AI-powered tool that improves audio quality by removing background noise and enhancing clarity in podcasts, videos, and music tracks.

An AI-powered article-to-audio converter for multilingual and accessible content.